Every answer, with its clause
Contracts and filings read into fields and questions answered with the clause they came from, with retention and the model pool decided before the first document is sent.
The clause is somewhere in four hundred pages
The renewal date is in a schedule, not the contract.
An associate finds it on the second read.
Five hundred NDAs. One question: which allow assignment?
The answer is a week of reading.
The client asks where the summary came from.
The draft cannot say.
Every answer needs its clause.Every document needs its rules.
The situations, and the guide that builds each
Every one is a build guide: the architecture, the policy, the code that was run, and what was measured.
Contracts into structured terms
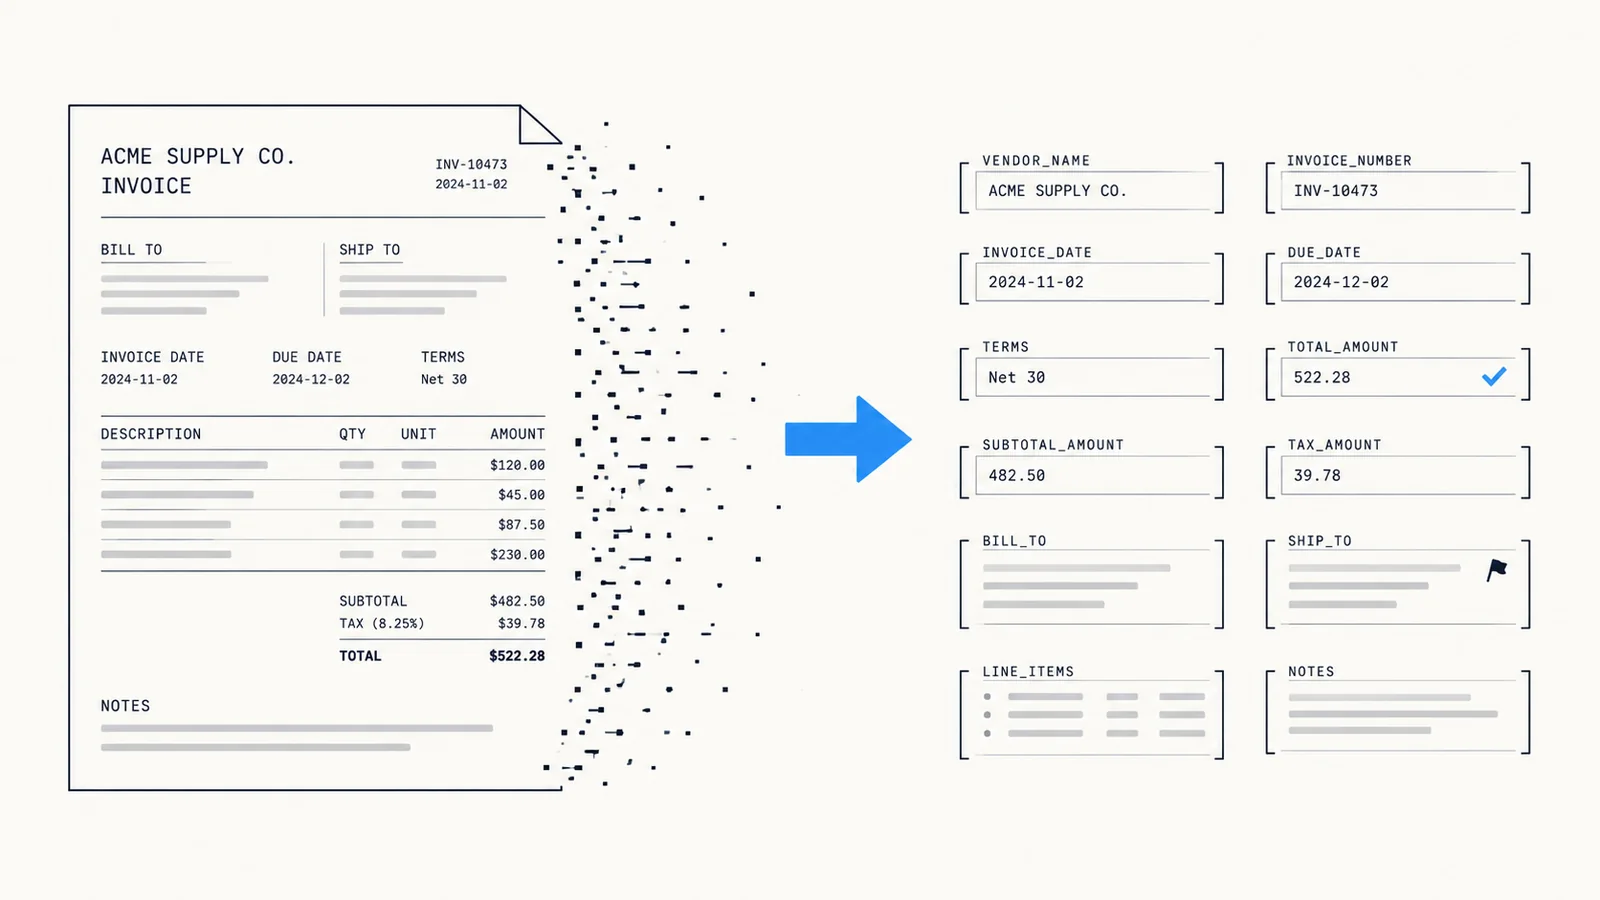
Parties, dates, renewal terms and obligations into fields that match a schema you define, with a review queue for what validation rejects and the model and cost stored with every record.
Build guide: Document extraction to JSON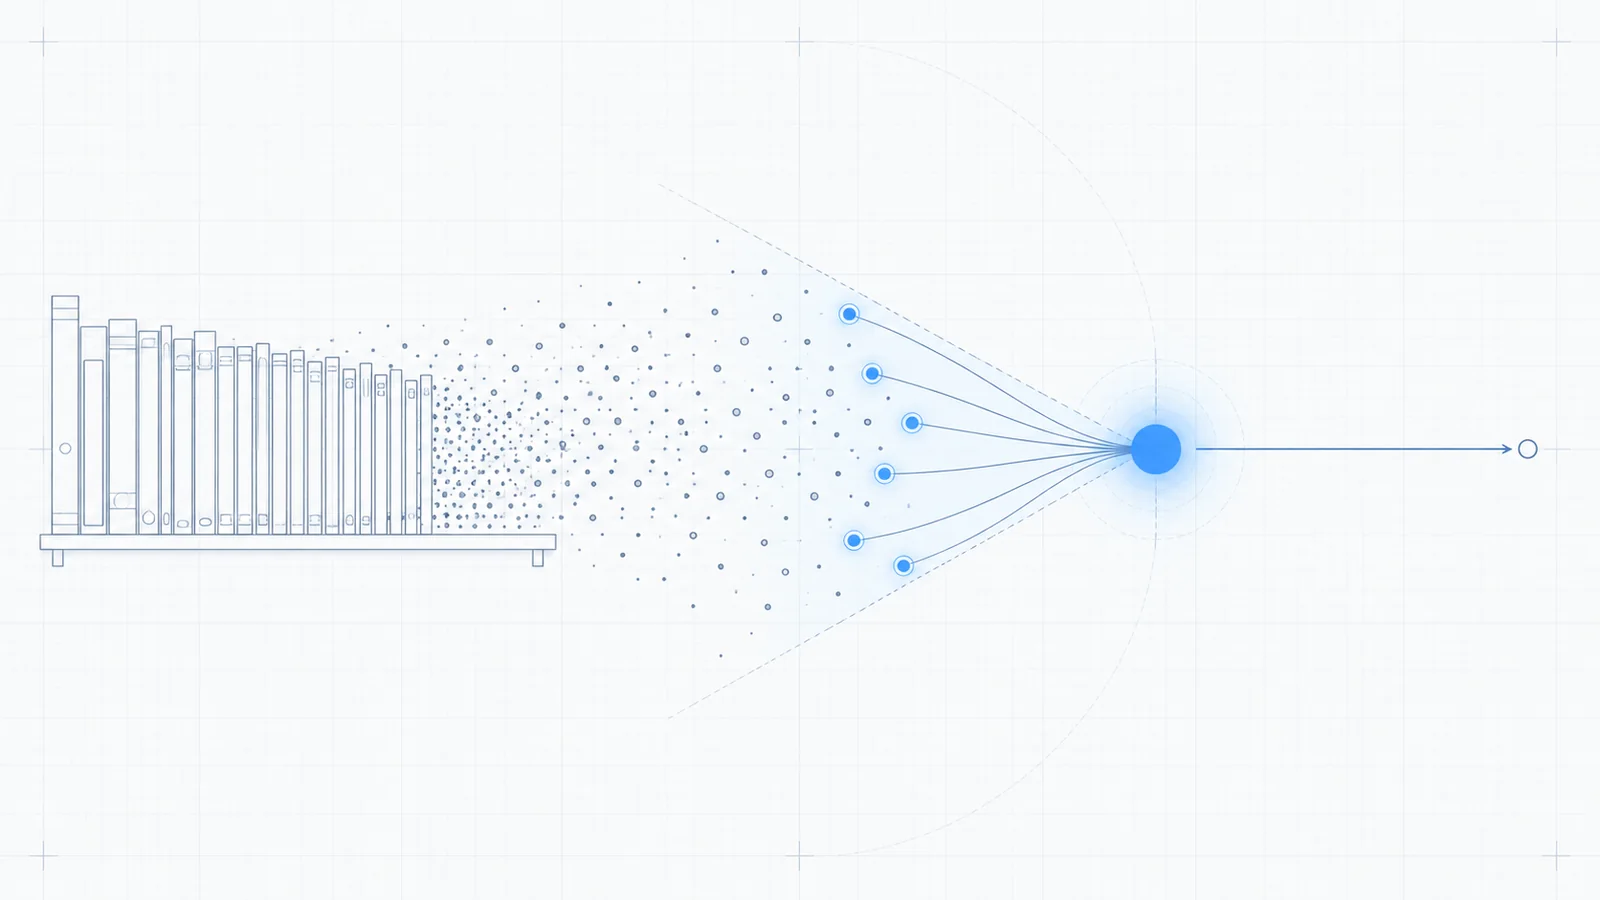
Questions across a document set, cited
Retrieval over contracts, filings and precedents with each answer cited to the clause it came from, routed so a lookup stays cheap and a cross-document question gets a strong model.
Build guide: RAG over a knowledge base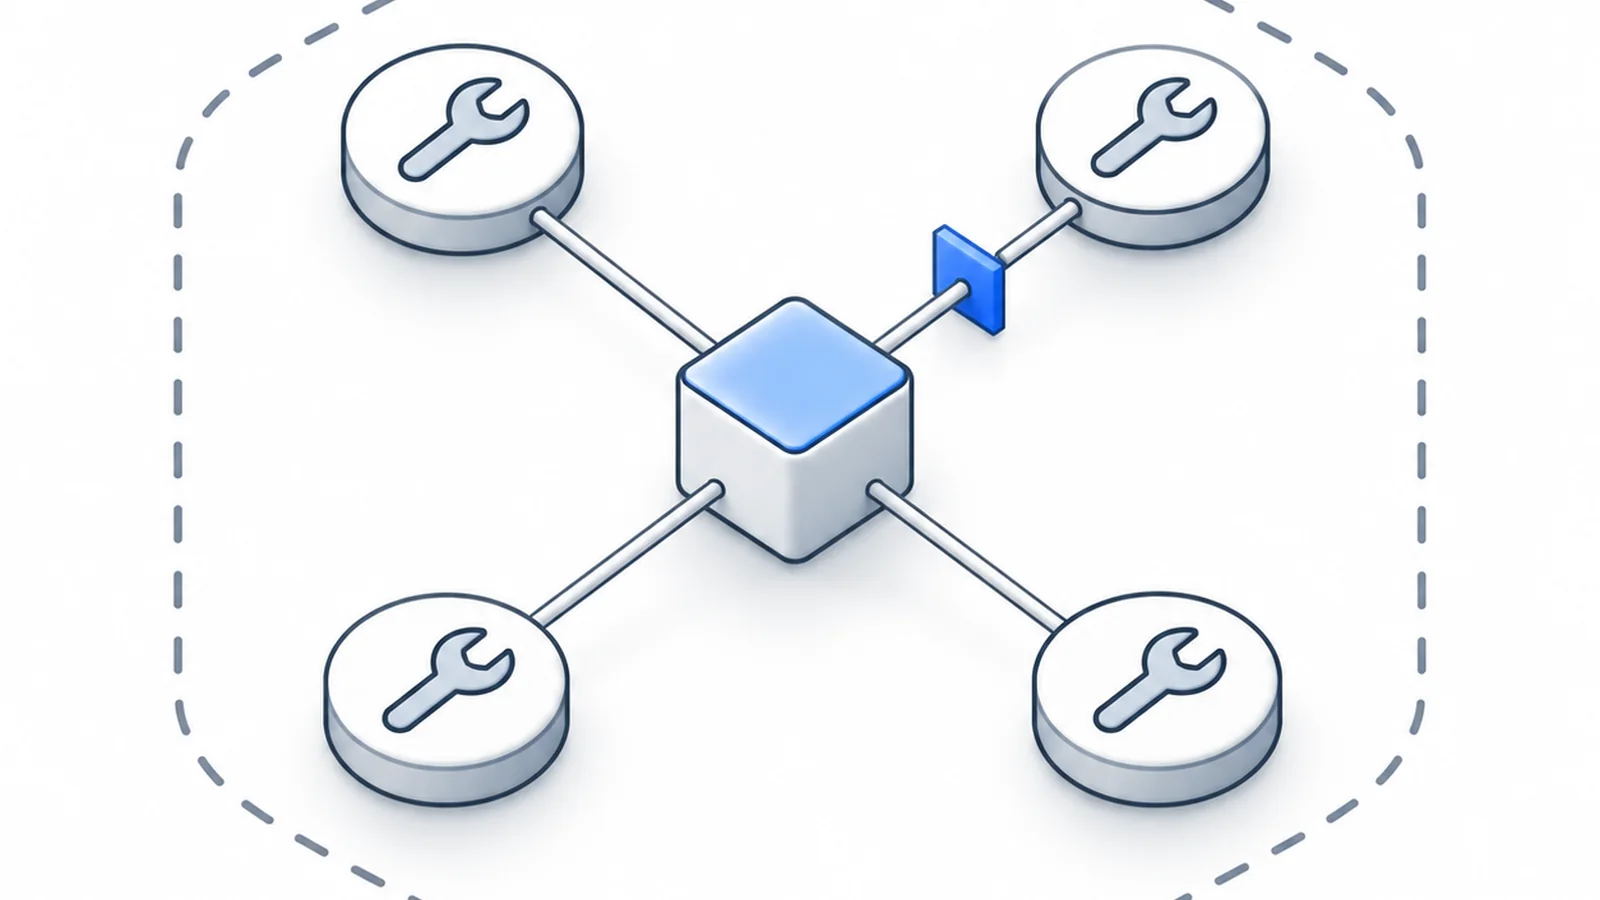
Matter tasks with a person on every write
An agent that reads matters and documents through tools named in a policy. Reads run at once; any change waits for approval, and every run is one record.
Build guide: Agents with tools and MCP
Client intake questions on your site
A chat that answers from your published pages with a citation, declines advice it should not give, and hands a matter-specific question to a person with the conversation attached.
Build guide: Customer support assistant
After-hours intake on the phone
A turn-based voice assistant that takes a caller's question and answers routine ones. Measured honestly at 7 to 13 seconds a turn today, which fits an intake line and not yet a conversation.
Build guide: Voice agentWhat changes for legal and professional services
Contracts and filings to extract from and to answer questions over, with retention and the model pool decided before the first document is sent.
Every answer names its clause
Answers cite the passage they used and extractions keep the document they came from, so a reviewer checks the source rather than the summary.
Retention decided first
Request content is kept for up to 30 days by default and not at all with zero retention on the key or the organisation. Decide it before the first document is sent.
A pool you can name
The routing policy names the models that may see a document, and nothing outside it is ever chosen. Your own provider keys or cloud accounts keep the call inside engagements you already hold.
Long documents, the right window
Each request can set a minimum context window, so only models that hold the whole document qualify, and the decision says which did.
Figures with a source
Every number here was measured by us and says when. Where nothing was measured, nothing is claimed.
| One short document extracted to JSON, non-streamed | 1.8 to 3.2 s | Measured 2026-10-14, three runs, client-side from India |
| Embedding plus rerank of a question | 1.4 to 5.0 s | Measured 2026-10-14, three runs, client-side from India |
| Streamed answer, first token, latency objective | 1.5 to 3.5 s | Measured 2026-10-14, three runs, client-side from India |
| Time to decide (classify and rank), live traffic | p50 18 to 31 ms | Gateway classifier timer, 2026-10-13 |
Questions from legal and professional services teams
Into a schema you define, with validation after the call and a review queue for what fails. Every record keeps the document reference, the model, the cost and the request id, so any term can be followed to the call that produced it.
Yes. The retrieval design numbers the passages it found and the prompt requires a citation after each sentence. When the passages do not settle a question, the answer says so rather than guessing.
Only the models in your routing policy pool, and a request can narrow it but never widen it. Your own provider keys or cloud accounts run the call inside the agreements you already hold.
For up to 30 days by default, deletable at any time, and not at all with zero retention on the key or the organisation. The routing decision is kept without the content.
Each request can set a minimum context window sized to the document, so only models that hold it qualify. Very long sets are split by section and extracted per part with the same schema.
Only what your own documents say, with a citation, and the prompt refuses everything outside them. A matter-specific question is handed to a person with the conversation attached.
No. Storage, search and matter systems stay where they are. The generation call goes to Inferbase with the model set to auto; the OpenAI SDK with the base URL changed is the whole integration.
The response carries the cost in micro-dollars, the same figure Usage shows, so each record can store what produced it. The verified invoice extraction on the guide cost about $0.0002; long contracts cost more and say so on their receipt.
Whichever models in your policy pool win on the objective for each request: a cheap model for a short NDA, a strong one for a cross-document question. The response always names the model that served.
Put intelligence in the middle.
One gateway in front of every model, with your policies applied and every decision on record. Start on the free plan with 5,000 requests a month, no card required.